Estimation theory is the part of signal processing that infers unknown quantities, such as a carrier frequency or a noise level, from noisy measurements. Every receiver does it: before it can demodulate a signal, it must estimate the carrier’s frequency and phase. This post introduces the vocabulary you need (estimator, bias, variance, mean square error) through one practical example and two Python checks.
A practical problem: recovering the carrier
Consider a double-sideband amplitude-modulated (DSB-AM) signal. The message $m(t)$ rides on a carrier at frequency $f_0$ with phase $\varphi_0$:
$$s(t; f_0, \varphi_0) = m(t)\cos(2\pi f_0 t + \varphi_0)$$
The received signal is this plus receiver noise $w(t)$:
$$x(t) = s(t; f_0, \varphi_0) + w(t)$$
To recover the message, the receiver multiplies the signal by an oscillator at the same frequency and phase, then low-pass filters the result. In a digital receiver the signal is first sampled, and this oscillator is a numerically controlled oscillator (NCO): a counter whose phase is set by a number, so the estimates can be written straight into it. The receiver does not know $f_0$ or $\varphi_0$, so it has to estimate them from $x(t)$.
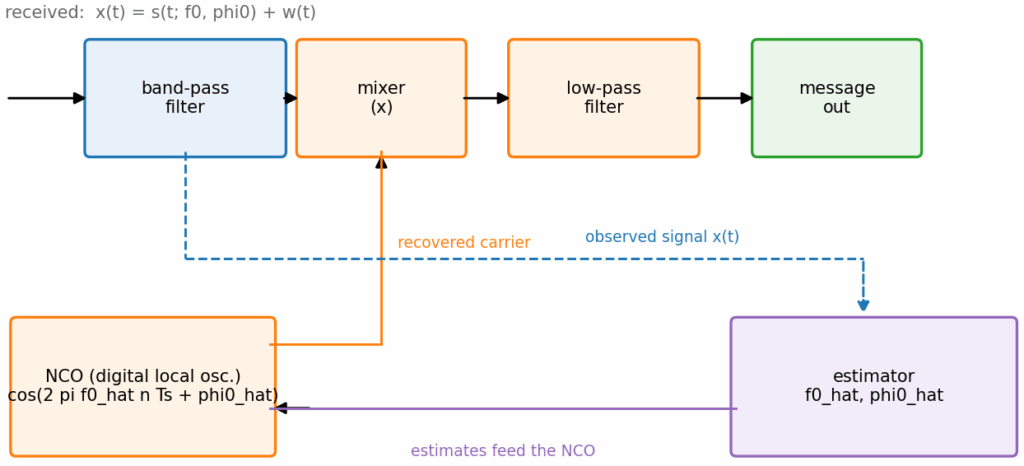
Figure 1: The estimator measures the carrier from the received signal and feeds it to the NCO. The mixer then removes the carrier, and the low-pass filter keeps the message.
The estimation model
Sample the received signal at $n = 0, \dots, N-1$. The samples have the form
$$x[n] = s[n; \theta] + w[n]$$
Here $\theta$ collects the unknown parameters, such as $f_0$ and $\varphi_0$. The noise $w[n]$ is random, so every observation of $x[n]$ is different. Because the data are random, any function of the data is random too.
An estimator $g(\mathbf{x})$ is a rule that maps the data $\mathbf{x} = (x[0], \dots, x[N-1])$ to an estimate $\hat{\theta} = g(\mathbf{x})$. The estimator is the recipe. The estimate is the number it gives for one dataset. Repeated datasets give a spread of estimates, described by a probability density function.
Judging an estimator: bias, variance, and MSE
Three quantities describe how good an estimator is:
- Bias: $b(\hat{\theta}) = E\lbrace \hat{\theta}\rbrace – \theta$, the difference between the average estimate and the true value.
- Variance: $\mathrm{var}(\hat{\theta}) = E\lbrace(\hat{\theta} – E\lbrace\hat{\theta}\rbrace)^2\rbrace$, how much the estimates scatter around their own average.
- Mean square error (MSE): $\mathrm{MSE}(\hat{\theta}) = E\lbrace(\hat{\theta} – \theta)^2\rbrace$, the average squared distance from the truth.
These three are linked by
$$\mathrm{MSE}(\hat{\theta}) = \mathrm{var}(\hat{\theta}) + b(\hat{\theta})^2$$
An estimator is unbiased when $b(\hat{\theta}) = 0$. Among all unbiased estimators, the one with the smallest variance is called the minimum variance unbiased estimator (MVUE). The MSE post explains why MSE is the usual overall measure.
Example: estimating the carrier phase
Suppose the frequency $f_0$ and amplitude $A$ are known, and only the phase $\varphi_0$ is unknown. Write $\omega_n = 2\pi f_0 n$ and correlate the samples with a cosine and a sine:
$$c = \sum_n x[n]\cos\omega_n, \qquad s = \sum_n x[n]\sin\omega_n$$
For $x[n] = A\cos(\omega_n + \varphi_0) + w[n]$ with a long record, $c \approx (NA/2)\cos\varphi_0$ and $s \approx -(NA/2)\sin\varphi_0$. The phase estimate is therefore
$$\hat{\varphi}_0 = \operatorname{atan2}(-s,\; c)$$
This estimator is essentially unbiased. Its variance is close to the Cramér-Rao bound $2\sigma^2/(NA^2)$, which is the best any unbiased estimator can do for this model. The CRLB introduction explains where that bound comes from.
Example: an estimator can be biased and still better
Now estimate the variance $\sigma^2$ of $N$ zero-mean samples. Two natural estimators are
$$\hat{\sigma}^{2,\mathrm{b}} = \frac{1}{N}\sum_{n=0}^{N-1}(x[n] – \bar{x})^2, \qquad \hat{\sigma}^{2,\mathrm{u}} = \frac{1}{N-1}\sum_{n=0}^{N-1}(x[n] – \bar{x})^2$$
Write $\mathrm{b}$ for biased and $\mathrm{u}$ for unbiased. The first divides by $N$ and is biased low, because the sample mean already absorbs part of the spread. Its bias is $-\sigma^2/N$. The second divides by $N-1$ and is unbiased. For $N = 8$ and $\sigma^2 = 1$, the closed-form MSE values are
$$\mathrm{MSE}^{\mathrm{b}} = \frac{2N-1}{N^2}\sigma^4 = \frac{15}{64} \approx 0.234, \qquad \mathrm{MSE}^{\mathrm{u}} = \frac{2}{N-1}\sigma^4 = \frac{2}{7} \approx 0.286$$
The biased estimator has the lower MSE, because its smaller variance outweighs its small bias. Unbiasedness is a desirable property, not the only one.
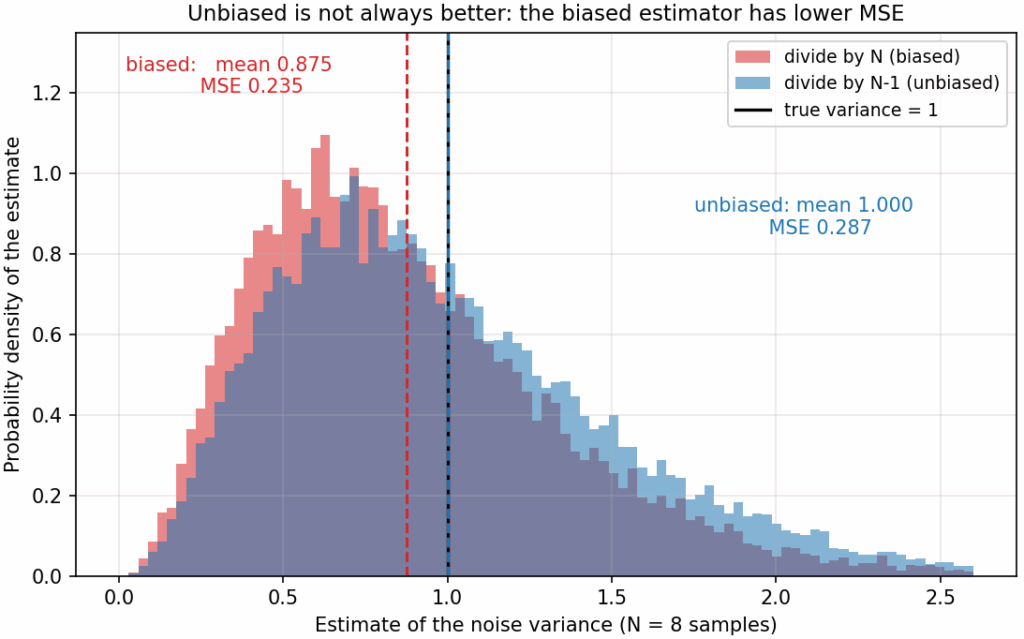
Figure 2: Estimates from 20,000 datasets of 8 samples each. The biased estimator (red) is shifted low but more tightly grouped. The unbiased one (blue) is centred on the truth but spread wider.
Python: the two checks
The code below runs both examples. The phase estimator is checked for bias and against the CRLB. The variance estimators are compared on bias, variance, and MSE.
import numpy as np

rng = np.random.default_rng(7)

# Part A: estimate the carrier phase of a tone with known frequency and amplitude
A, f0, sigma, N = 1.0, 0.08, 0.7, 100
phi_true = 0.9
n = np.arange(N)
omega = 2 * np.pi * f0 * n
trials = 20_000
x = A * np.cos(omega + phi_true) + sigma * rng.standard_normal((trials, N))

c = x @ np.cos(omega)                 # correlate with cosine
s = x @ np.sin(omega)                 # correlate with sine
phi_hat = np.arctan2(-s, c)           # closed-form phase estimate

crlb = 2 * sigma ** 2 / (N * A ** 2)  # CRLB for phase (Fisher information = N A^2 / (2 sigma^2))
print("Part A: phase estimate of a tone")
print(f"  true phase {phi_true:.3f}, mean estimate {phi_hat.mean():.4f}, bias {phi_hat.mean() - phi_true:+.4f}")
print(f"  variance {phi_hat.var():.6f}, CRLB {crlb:.6f}, ratio {phi_hat.var() / crlb:.3f}")

# Part B: biased and unbiased estimators of the noise variance
sigma2 = 1.0
N_small = 8
rng_b = np.random.default_rng(11)
y = np.sqrt(sigma2) * rng_b.standard_normal((trials, N_small))
var_biased = y.var(axis=1, ddof=0)    # divides by N
var_unbiased = y.var(axis=1, ddof=1)  # divides by N - 1
print("Part B: variance estimators with N =", N_small)
print(f"  biased   (/N):   mean {var_biased.mean():.4f}, variance {var_biased.var():.4f}, MSE {np.mean((var_biased - sigma2) ** 2):.4f}")
print(f" unbiased (/N-1): mean {var_unbiased.mean():.4f}, variance {var_unbiased.var():.4f}, MSE {np.mean((var_unbiased - sigma2) ** 2):.4f}")Running it prints:
Part A: phase estimate of a tone
  true phase 0.900, mean estimate 0.9003, bias +0.0003
  variance 0.010004, CRLB 0.009800, ratio 1.021
Part B: variance estimators with N = 8
  biased   (/N):   mean 0.8753, variance 0.2195, MSE 0.2351
unbiased (/N-1): mean 1.0004, variance 0.2867, MSE 0.2867The phase estimate has essentially zero bias, and its variance is about 2% above the bound. For the variance estimators, the simulated MSE values match the closed forms: about 0.235 for the biased estimator and 0.287 for the unbiased one. The biased estimator wins on MSE, as predicted.
Three common misunderstandings
- “Unbiased means accurate.” Unbiased means right on average. A wide spread can still make a single estimate far off, so variance and MSE matter too.
- “The estimate is the estimator.” The estimator is the rule $g(\mathbf{x})$. The estimate is its output for one dataset, and it changes from dataset to dataset.
- “A biased estimator is always worse.” It can have lower MSE, as the variance example shows. The right choice depends on the overall error you care about.
What comes next
This post sets up the vocabulary. The next steps are the MSE post, the MVUE post for the best unbiased estimator, and the CRLB introduction for the limit on variance. The maximum likelihood post covers a general method for building estimators.
Summary
- Estimation theory infers unknown parameters from random observations.
- An estimator maps data to an estimate. The estimate is random because the data are random.
- Bias, variance and MSE describe an estimator’s quality, and MSE = variance + bias².
- Unbiased estimators are useful, but a biased estimator can have lower MSE.
- Receivers use estimators for carrier frequency, phase and timing.
Learning path: Estimation theory
- Estimation theory introduction (this post)
- The mean square error
- Minimum-variance unbiased estimators
- Cramér-Rao lower bound introduction
- Fisher information and the score
- Maximum likelihood estimation
- Efficient estimators and the CRLB
- Cramér-Rao bound for phase estimation
References
- Steven M. Kay, Fundamentals of Statistical Signal Processing, Volume I: Estimation Theory, Prentice Hall, 1993. Catalog record. The standard textbook on this material.
- Estimation theory (Wikipedia): an overview of estimators and their criteria.
- Bias of an estimator (Wikipedia): the definition and examples of bias.
- Mean squared error (Wikipedia): the MSE and its bias-variance decomposition.
- Bessel’s correction (Wikipedia): why the sample variance divides by $N-1$.
- Minimum-variance unbiased estimator (Wikipedia): the optimal unbiased estimator.
- Atan2 (Wikipedia): the two-argument arctangent used for the phase estimate.
Estimation and detection in communications. The same estimators drive carrier recovery, channel estimation and timing synchronisation in digital receivers. The GaussianWaves eBooks cover some of that classical side with runnable Python and Matlab code.