Keywords: maximum likelihood estimation, statistical method, probability distribution, MLE, models, practical applications, finance, economics, natural sciences.
Introduction
Maximum Likelihood Estimation (MLE) is a statistical method used to estimate the parameters of a probability distribution by finding the set of values that maximize the likelihood function of the observed data. In other words, MLE is a method of finding the most likely values of the unknown parameters that would have generated the observed data.
The likelihood function is a function that describes the probability of observing the data given the parameters of the probability distribution. The MLE method seeks to find the set of parameter values that maximizes this likelihood function.
For example, suppose we have a set of data that we believe to be normally distributed, but we do not know the mean or variance of the distribution. We can use MLE to estimate these parameters by finding the mean and variance that maximize the likelihood function of the observed data.
The MLE method is widely used in statistical inference, hypothesis testing, and model fitting in many areas, including economics, finance, engineering, and the natural sciences. MLE is a powerful and flexible method that can be applied to a wide range of statistical models, making it a valuable tool in data analysis and modeling.
Difference between MLE and MLD
Maximum likelihood estimation (MLE) and maximum likelihood decoding (MLD) are two different concepts used in different contexts.
Maximum likelihood estimation is a statistical method used to estimate the parameters of a probability distribution based on a set of observed data. The goal is to find the set of parameter values that maximize the likelihood function of the observed data. MLE is commonly used in statistical inference, hypothesis testing, and model fitting.
On the other hand, maximum likelihood decoding (MLD) is a method used in digital communications and signal processing to decode a received signal that has been transmitted through a noisy channel. The goal is to find the transmitted message that is most likely to have produced the received signal, based on a given probabilistic model of the channel.
In maximum likelihood decoding, the receiver calculates the likelihood of each possible transmitted message, given the received signal and the channel model. The maximum likelihood decoder then selects the transmitted message that has the highest likelihood as the decoded message.
While both MLE and MLD involve the concept of maximum likelihood, they are used in different contexts. MLE is used in statistical estimation, while MLD is used in digital communications and signal processing for decoding.
MLE applied to communication systems
Maximum Likelihood estimation (MLE) is an important tool in determining the actual probabilities of the assumed model of communication.
In reality, a communication channel can be quite complex and a model becomes necessary to simplify calculations at decoder side.The model should closely approximate the complex communication channel. There exist a myriad of standard statistical models that can be employed for this task; Gaussian, Binomial, Exponential, Geometric, Poisson,etc., A standard communication model is chosen based on empirical data.
Each model mentioned above has unique parameters that characterizes them. Determination of these parameters for the chosen model is necessary to make them closely model the communication channel at hand.
Suppose a binomial model is chosen (based on observation of data) for the error events over a particular channel, it is essential to determine the probability of succcess (\(p\)) of the binomial model.
If a Gaussian model (normal distribution!!!) is chosen for a particular channel then estimating mean (\(\mu\)) and variance (\(\sigma^{2}\)) are necessary so that they can be applied while computing the conditional probability of p(y received | x sent)
Similarly estimating the mean number of events within a given interval of time or space (\(\lambda\)) is a necessity for a Poisson distribution model.
Maximum likelihood estimation is a method to determine these unknown parameters associated with the corresponding chosen models of the communication channel.
Python code example for MLE
The crossover probability of a binary symmetric channel is a binomial parameter, and its maximum likelihood estimate has a closed form. There is a trap in how the data are collected.
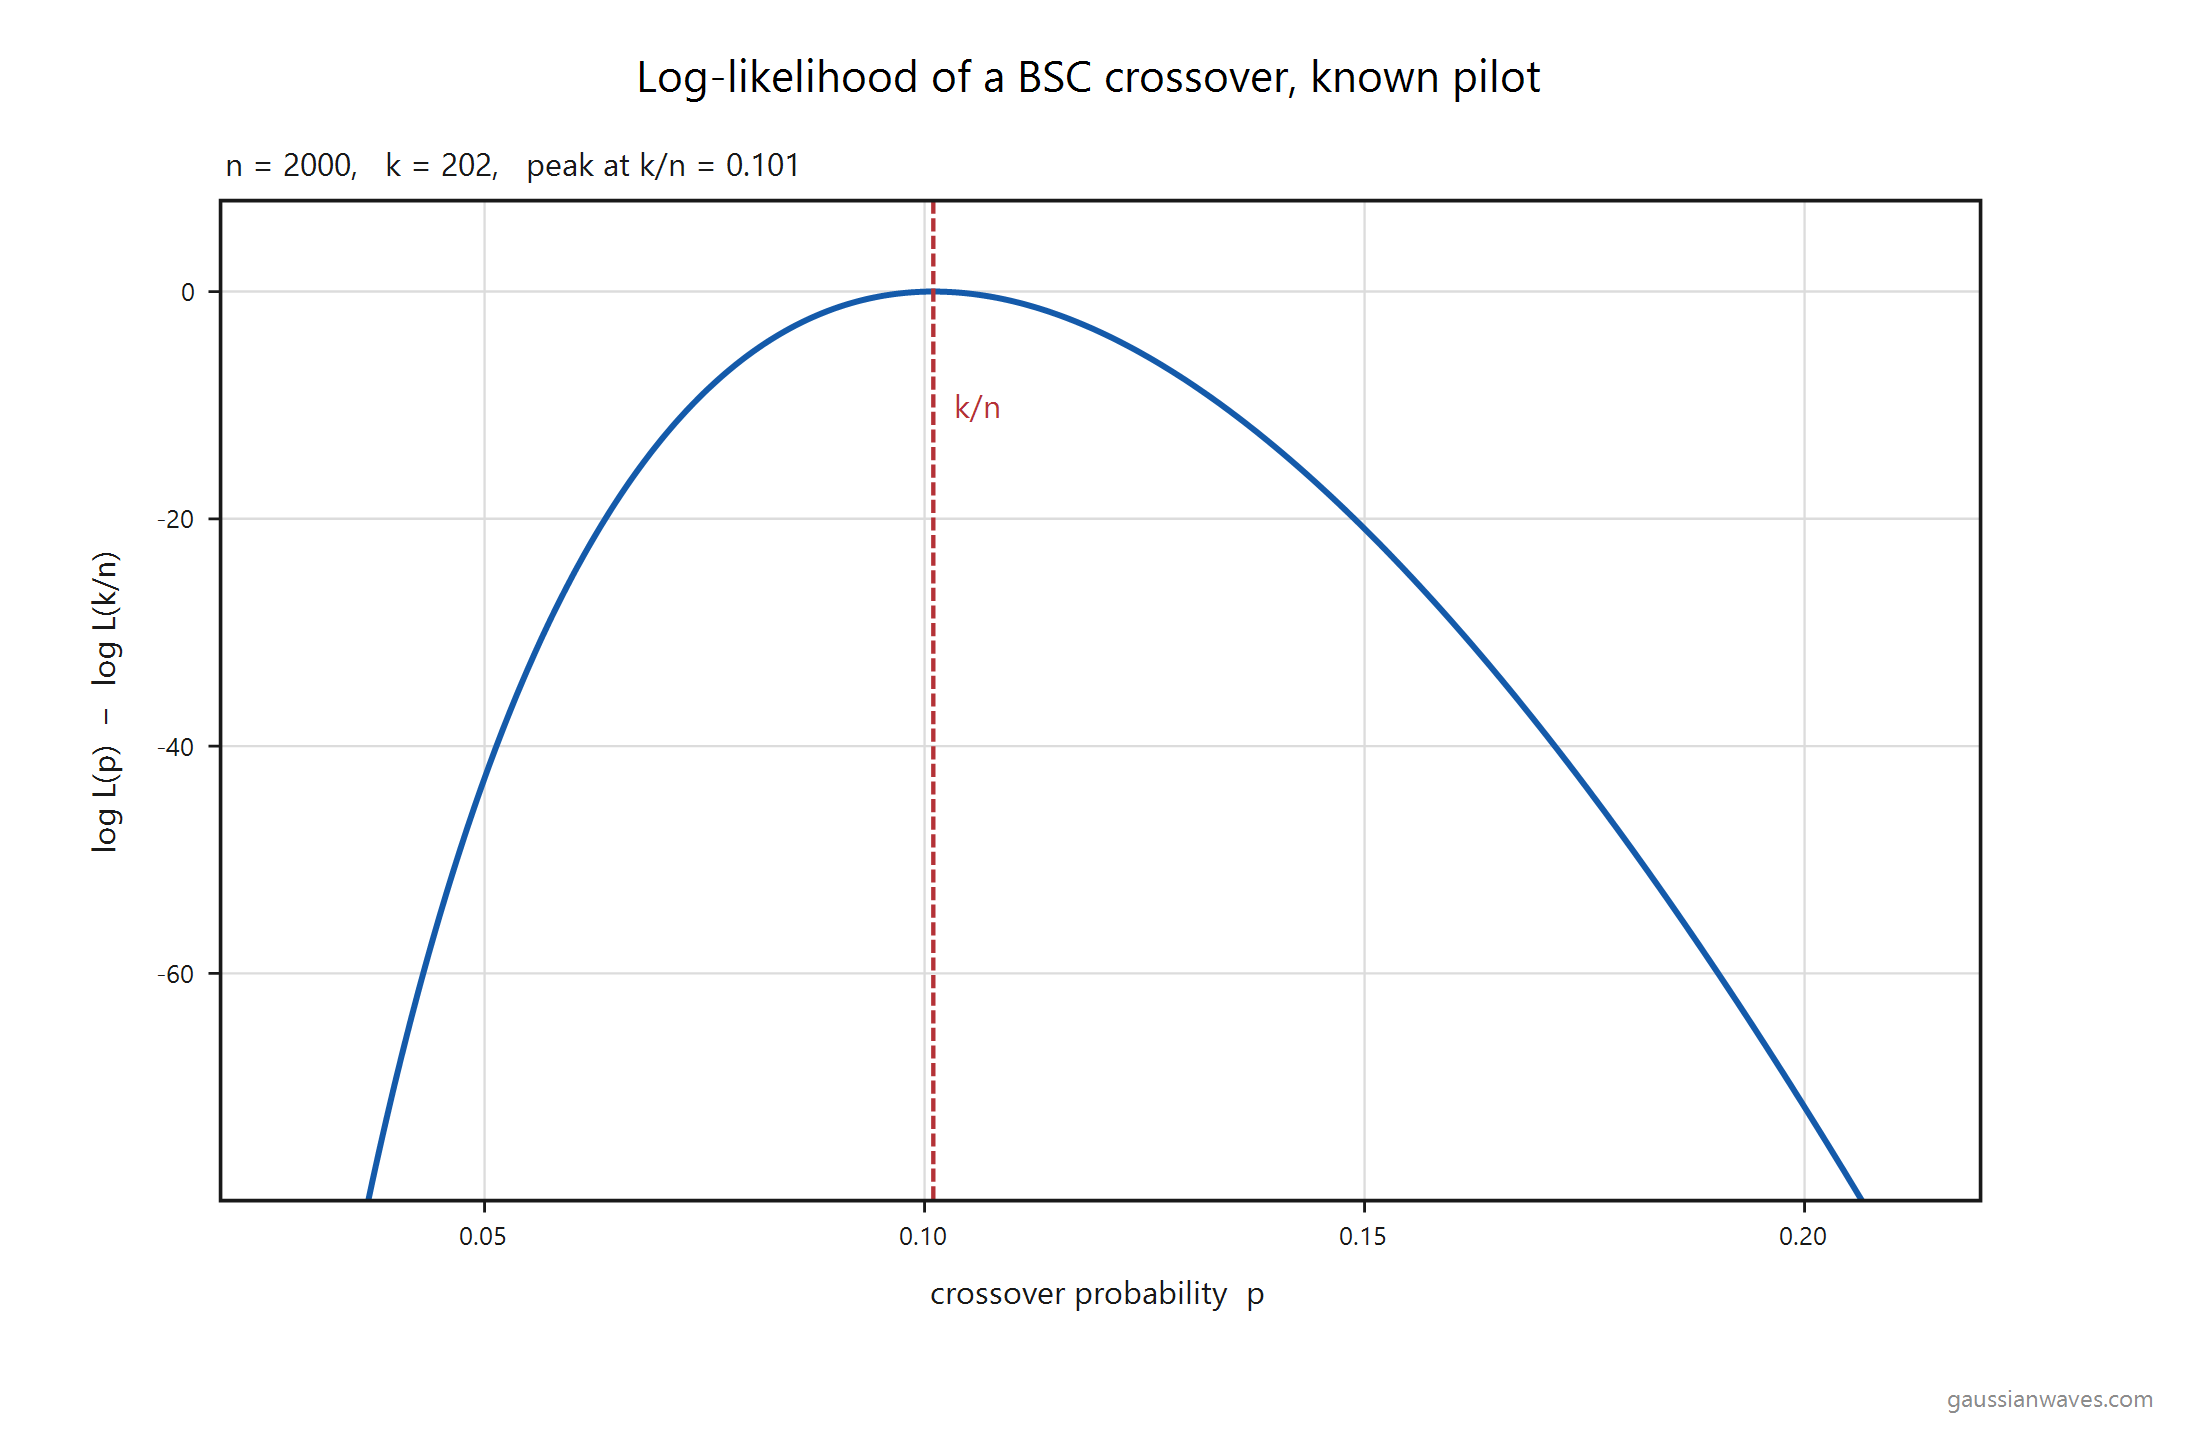
If the source bits are fair, the bits that come out of a BSC are also fair, for every value of the crossover probability \(p\). Counting the ones in the received sequence estimates \(1/2\), not \(p\). The crossover is visible only when the receiver can compare the received bits with the bits that were sent, as it can on a known pilot. Each comparison is then a Bernoulli trial with success probability \(p\), the number of disagreements \(K\) in \(n\) bits is binomial, and the likelihood
\[L(p) = \binom{n}{k} p^{k}(1-p)^{n-k}\]is maximised at \(\hat{p} = k/n\). A numerical optimiser is unnecessary, and it is a useful check: a correct optimiser must land on that ratio. The Gaussian case is just as direct. For independent samples from \(N(\mu,\sigma^2)\) the ML estimates are the sample mean and the mean of the squared deviations. The variance estimate divides by \(n\), not by \(n-1\). The unbiased sample variance is a different estimator.
A short run with a known pilot makes the closed form obvious, and the Gaussian estimates are printed beside it.
import numpy as np

rng = np.random.default_rng(0)
n = 2000
p_true = 0.1

tx = rng.integers(0, 2, size=n)
rx = tx ^ (rng.random(n) < p_true)
k = int(np.sum(tx != rx))
p_hat = k / n
print("pilot comparison: k = %d,  p_hat = %.4f,  true p = %.2f" % (k, p_hat, p_true))

# Received bits alone do not carry p. Their mean stays near 1/2.
print("mean of received bits (not an estimate of p): %.4f" % rx.mean())

# Gaussian ML estimates. The variance divides by n.
mu_true, sigma = 1.5, 0.8
samples = rng.normal(mu_true, sigma, size=n)
mu_hat = samples.mean()
var_hat = np.mean((samples - mu_hat) ** 2)
print("Gaussian: mu_hat = %.3f,  sigma2_hat = %.3f (true %.3f)" % (mu_hat, var_hat, sigma ** 2))
Figure 1 is that curve for one pilot of \(n = 2000\) bits that recorded \(k = 202\) disagreements. The peak is at \(k/n = 0.101\). Another run of the listing moves the peak, and it still lands on \(k/n\).
Reference :
[1] – Maximum Likelihood Estimation – a detailed explanation by S.Purcell
Related Topics: