Coding path:
Hamming codes →
Hard vs soft decoding →
Maximum-likelihood decoding
In one sentence: A Hamming code adds parity bits at power-of-two positions so the binary syndrome points directly at the flipped bit — correcting any single error in the block.
Keywords: Hamming code, error-correction code, digital communication, data storage, reliable transmission, computer memory systems, satellite communication systems, single-bit error, two-bit errors.
What is a Hamming code?
Hamming codes are error-correcting codes used in digital communication and data storage to detect and correct errors introduced during transmission or storage. Richard Hamming introduced them in 1950 in a paper in the Bell System Technical Journal.
The idea is redundancy. Extra bits, called parity bits, are appended to the message so the receiver can check the received word for consistency. With the right arrangement of parity bits, the check results point to the single bit that went wrong.
A binary Hamming code has minimum distance 3. (For a refresher on Hamming distance, see Euclidean and Hamming distances.) That gives two capabilities, and they trade off:
- As a corrector, it fixes any single-bit error.
- As a detector, a nonzero syndrome flags any one- or two-bit error.
A decoder cannot do both at full strength. If it corrects single errors, a double error looks like a single error in a different codeword, so it is silently miscorrected. The (7,4) Hamming code is a perfect code (see perfect code): every nonzero syndrome matches a single-bit error, so no syndrome is left over to say “two errors detected”. The worked example below shows this.
Memory systems that must correct one error and also detect a double error add an overall parity bit. The result is an extended Hamming code with minimum distance 4. It is the SECDED (single-error correction, double-error detection) code used in ECC memory.
Parameters of Hamming codes
For every integer $p \geq 3$ (the number of parity bits), there is a binary Hamming code with parameters $(2^p-1,\ 2^p-p-1)$. The first number is the codeword length $n$, and the second is the number of information bits $k$.
| Quantity | Formula | (7,4) code |
|---|---|---|
| Codeword length | $n = 2^p – 1$ | 7 |
| Information bits | $k = 2^p – p – 1$ | 4 |
| Parity bits | $n – k = p$ | 3 |
| Minimum distance | $d_{\min} = 3$ | 3 |
| Error-correcting capability | $t = 1$ | 1 |
With $p = 3$ you get the basic (7,4) code: 4 message bits, 3 parity bits, and 7-bit codewords.
Systematic and non-systematic encoding
Block codes are classified by where the message bits sit in the codeword.
- Systematic: the message bits appear unchanged in the codeword, so data and parity bits are easy to separate.
- Non-systematic: data and parity bits are interleaved.
Hamming’s original construction is non-systematic. Reordering the columns turns it into a systematic code, so both forms describe the same code.
Constructing the (7,4) Hamming code
Write a codeword as $[D_7, D_6, D_5, P_4, D_3, P_2, P_1]$. The parity bits sit at the power-of-two positions 1, 2 and 4. To find which bits each parity bit covers, write every position in binary. Parity bit $P_j$ covers each position whose binary form has a 1 in bit $j$, counting from the least significant bit.
| Parity bit | Positions covered | Rule |
|---|---|---|
| $P_1$ | 1, 3, 5, 7 | bit 0 is 1 (001, 011, 101, 111) |
| $P_2$ | 2, 3, 6, 7 | bit 1 is 1 (010, 011, 110, 111) |
| $P_4$ | 4, 5, 6, 7 | bit 2 is 1 (100, 101, 110, 111) |
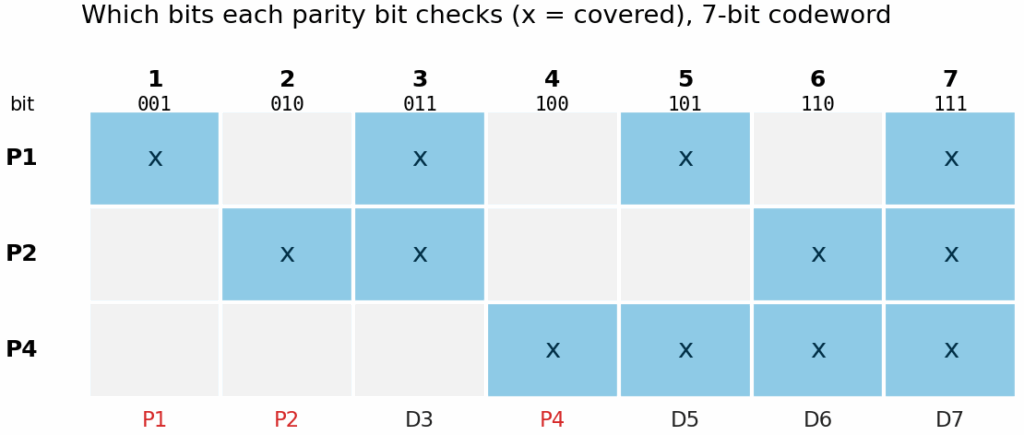
With even parity, the bits covered by each parity bit (including the parity bit itself) XOR to 0:
$$P_1 = D_3 \oplus D_5 \oplus D_7, \qquad P_2 = D_3 \oplus D_6 \oplus D_7, \qquad P_4 = D_5 \oplus D_6 \oplus D_7$$
Renaming the bits in order gives the systematic (7,4) code used from here on. It has four data bits $D_1 D_2 D_3 D_4$ followed by three parity bits $P_1 P_2 P_3$:
$$P_1 = D_1 \oplus D_2 \oplus D_3, \qquad P_2 = D_2 \oplus D_3 \oplus D_4, \qquad P_3 = D_1 \oplus D_3 \oplus D_4$$
This is the same code as the non-systematic one. Only the column order has changed.
Encoding with the generator matrix
The encoder uses a generator matrix $\mathbf{G} = [\,\mathbf{I}_4 \mid \mathbf{P}\,]$. Each row corresponds to one data bit and shows which parity bits it affects. With the columns ordered $D_1\, D_2\, D_3\, D_4\, P_1\, P_2\, P_3$:
$$\mathbf{G}=\begin{bmatrix}1&0&0&0&1&0&1\\0&1&0&0&1&1&0\\0&0&1&0&1&1&1\\0&0&0&1&0&1&1\end{bmatrix}$$
The row for $D_1$ ends in 1 0 1, so $D_1$ affects $P_1$ and $P_3$. Likewise $D_2$ affects $P_1$ and $P_2$, $D_3$ affects all three parity bits, and $D_4$ affects $P_2$ and $P_3$.
A 4-bit message $\mathbf{m}$ is encoded as
$$\mathbf{c} = \mathbf{m}\,\mathbf{G} \pmod 2$$
All arithmetic is modulo 2, which is arithmetic over the binary field GF(2). For example, with $\mathbf{m} = [1\ 0\ 1\ 1]$: $P_1 = 1 \oplus 0 \oplus 1 = 0$, $P_2 = 0 \oplus 1 \oplus 1 = 0$ and $P_3 = 1 \oplus 1 \oplus 1 = 1$. So
$$\mathbf{c} = [1\ 0\ 1\ 1\ 0\ 0\ 1]$$
Because there are only 16 possible messages, the encoder can use a look-up table. Table 2 lists all 16 codewords.
Table 2: All 16 codewords of the systematic (7,4) Hamming code
| Message $\mathbf{m}$ | Codeword $\mathbf{c}$ | Message $\mathbf{m}$ | Codeword $\mathbf{c}$ |
|---|---|---|---|
| 0000 | 0000000 | 1000 | 1000101 |
| 0001 | 0001011 | 1001 | 1001110 |
| 0010 | 0010111 | 1010 | 1010010 |
| 0011 | 0011100 | 1011 | 1011001 |
| 0100 | 0100110 | 1100 | 1100011 |
| 0101 | 0101101 | 1101 | 1101000 |
| 0110 | 0110001 | 1110 | 1110100 |
| 0111 | 0111010 | 1111 | 1111111 |
Decoding: syndrome decoding
The parity-check matrix is $\mathbf{H} = [\,\mathbf{P}^T \mid \mathbf{I}_3\,]$, which for this code is:
$$\mathbf{H}=\begin{bmatrix}1&1&1&0&1&0&0\\0&1&1&1&0&1&0\\1&0&1&1&0&0&1\end{bmatrix}$$
Every codeword satisfies $\mathbf{c}\,\mathbf{H}^T = \mathbf{0}$. This follows from $\mathbf{G}\,\mathbf{H}^T = \mathbf{0}$, which is shown in the properties section below.
The receiver gets $\mathbf{r} = \mathbf{c} + \mathbf{e}$, where $\mathbf{e}$ is the error pattern introduced by the channel (often modelled as a binary symmetric channel). The syndrome is
$$\mathbf{s} = \mathbf{r}\,\mathbf{H}^T = (\mathbf{c} + \mathbf{e})\,\mathbf{H}^T = \mathbf{e}\,\mathbf{H}^T$$
The syndrome depends only on the error pattern, not on the transmitted codeword. This is the core idea of syndrome decoding.
For a single error at position $i$, $\mathbf{e}$ has a single 1 in position $i$, so $\mathbf{s}$ equals column $i$ of $\mathbf{H}$. This gives the decoding rule:
- If $\mathbf{s} = \mathbf{0}$, accept $\mathbf{r}$ as a codeword.
- Otherwise, find the column of $\mathbf{H}$ that equals $\mathbf{s}$, and flip the bit at that position.
Table 3: Syndrome for each single-bit error (syndrome written top to bottom)
| Error position | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
|---|---|---|---|---|---|---|---|
| Syndrome $\mathbf{s}$ | 101 | 110 | 111 | 011 | 100 | 010 | 001 |
In the classic presentation, the columns of $\mathbf{H}$ are arranged so that column $i$ is the binary form of $i$. Then the syndrome, read as a binary number, is the error position directly. The systematic $\mathbf{H}$ above is a column reordering of that form, so use the lookup table in Table 3 instead.
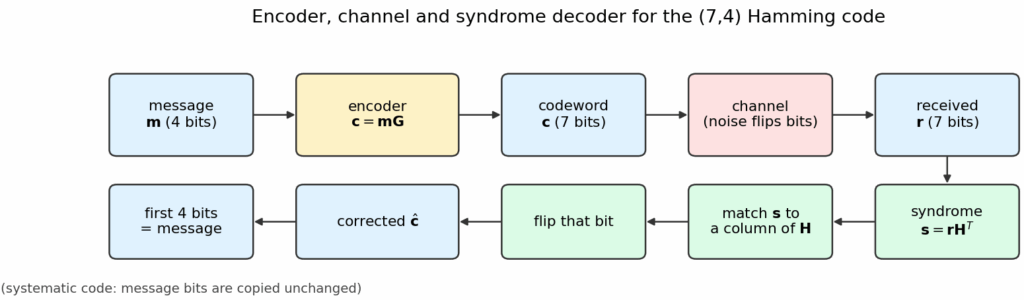
Figure 2: The encoder and syndrome decoder as a flow. The decoder never needs the message: it works only on the received word.
Worked example: single error
Send $\mathbf{c} = [1\ 0\ 1\ 1\ 0\ 0\ 1]$ and flip bit 3. The receiver gets $\mathbf{r} = [1\ 0\ 0\ 1\ 0\ 0\ 1]$.
The syndrome is $\mathbf{s} = [1\ 1\ 1]$, which matches column 3 of $\mathbf{H}$. Flip bit 3 and you recover $[1\ 0\ 1\ 1\ 0\ 0\ 1]$.
Worked example: double error
Now flip bits 1 and 2 of the same codeword. The receiver gets $\mathbf{r} = [0\ 1\ 1\ 1\ 0\ 0\ 1]$.
The syndrome is $\mathbf{s} = [0\ 1\ 1]$, which matches column 4 of $\mathbf{H}$. The decoder therefore flips bit 4 and outputs $[0\ 1\ 1\ 0\ 0\ 0\ 1]$. That is a valid codeword, but it differs from the one sent in three positions. The double error has been silently miscorrected.
Performance: when does the code pay off?
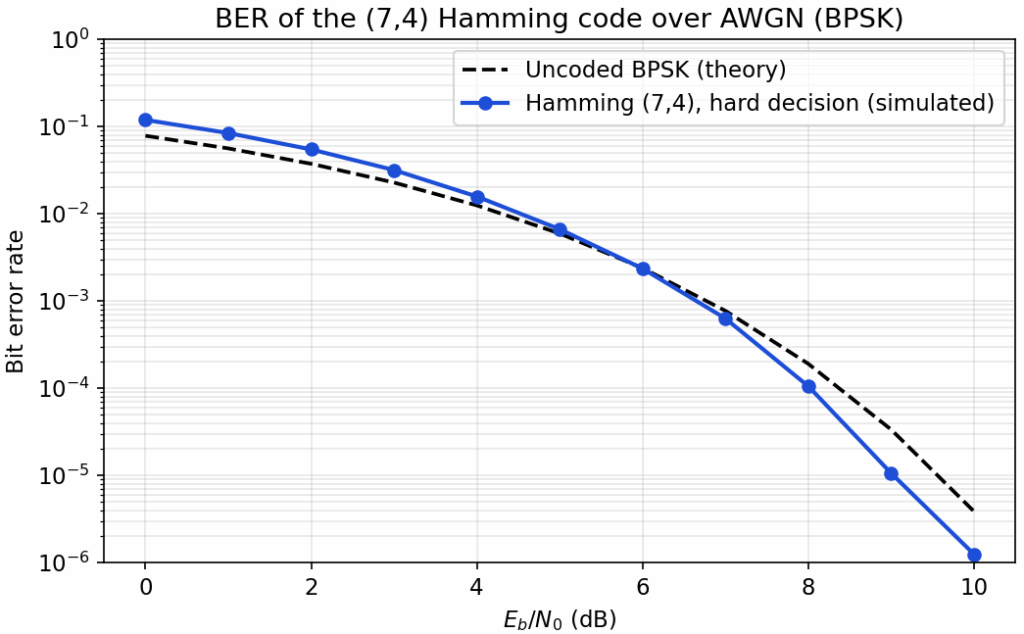
The parity bits are not free. The code has rate $R = 4/7$, so each channel bit carries less energy. Simulating the hard-decision decoder over AWGN with BPSK (400,000 random codewords per point) gives the curve below. Each channel bit is flipped with probability $p = Q\left(\sqrt{2R\,E_b/N_0}\right)$, where $Q(\cdot)$ is the Q-function and $E_b$ is the energy per information bit. For the uncoded reference curve and the simulation method, see the BPSK BER simulation post.
| $E_b/N_0$ (dB) | 0 | 2 | 4 | 6 | 8 | 10 |
|---|---|---|---|---|---|---|
| Uncoded BPSK | 7.9e-2 | 3.8e-2 | 1.3e-2 | 2.4e-3 | 1.9e-4 | 3.9e-6 |
| Hamming (7,4), hard decision | 1.2e-1 | 5.5e-2 | 1.6e-2 | 2.4e-3 | 1.1e-4 | 1.3e-6 |
Two lessons follow:
- The code only pays off at moderate to high SNR. At 10 dB it reduces the BER by about a factor of three.
- Hard decisions throw away reliability information. Soft-decision decoding recovers more of the coding gain from the same parity structure.
Some properties of generator and parity-check matrices
The generator matrix and the parity-check matrix satisfy
$$\mathbf{G}\,\mathbf{H}^T = \mathbf{0}$$
When $\mathbf{G}$ is in standard form, $\mathbf{G} = [\,\mathbf{I}_k \mid \mathbf{P}\,]$, the corresponding parity-check matrix is
$$\mathbf{H} = [\,-\mathbf{P}^T \mid \mathbf{I}_{n-k}\,]$$
Over GF(2), every element is its own additive inverse, because $1 + 1 = 0$. The minus sign therefore drops out, and the parity-check matrix of a binary code in systematic form is
$$\mathbf{H} = [\,\mathbf{P}^T \mid \mathbf{I}_{n-k}\,]$$
Code: encoder and syndrome decoder
Both listings below were run and give the same results. The MATLAB version uses base MATLAB only (bitget, no Communications Toolbox).
% (7,4) systematic Hamming code: encoder, syndrome decoder, single-error test
G = [1 0 0 0 1 0 1;
     0 1 0 0 1 1 0;
     0 0 1 0 1 1 1;
     0 0 0 1 0 1 1];
H = [1 1 1 0 1 0 0;
     0 1 1 1 0 1 0;
     1 0 1 1 0 0 1];

% Build the codebook of all 16 codewords (rows = messages, MSB first)
k = 4;
m = zeros(2^k, k);
for i = 0:2^k-1
    m(i+1, :) = bitget(i, k:-1:1);
end
codebook = mod(m * G, 2);

% Encode a message, flip one bit, then correct it
msg = [1 0 1 1];
c = mod(msg * G, 2);
for flipPos = [0 3]                    % 0 = no error, 3 = flip bit 3
    r = c;
    if flipPos > 0
        r(flipPos) = 1 - r(flipPos);
    end
    s = mod(r * H.', 2);               % syndrome
    corrected = r;
    errLoc = [];
    if any(s)
        errLoc = find(all(H == s.', 1)); % column of H equal to the syndrome
        corrected(errLoc) = 1 - corrected(errLoc);
    end
    fprintf('flip=%d syndrome=%s flipped=%s correct=%d\n', ...
        flipPos, mat2str(s), mat2str(errLoc), all(corrected == c));
endimport numpy as np
G = np.array([
[1, 0, 0, 0, 1, 0, 1],
[0, 1, 0, 0, 1, 1, 0],
[0, 0, 1, 0, 1, 1, 1],
[0, 0, 0, 1, 0, 1, 1],
])
H = np.array([
[1, 1, 1, 0, 1, 0, 0],
[0, 1, 1, 1, 0, 1, 0],
[1, 0, 1, 1, 0, 0, 1],
])
def encode(msg):
return (np.array(msg) @ G) % 2
def decode(r):
r = np.array(r)
s = (r @ H.T) % 2 # syndrome
if not s.any():
return r, None # zero syndrome: no error detected
# Every nonzero syndrome equals some column of H (the code is perfect).
pos = next(i for i in range(H.shape[1]) if np.array_equal(H[:, i], s))
r[pos] ^= 1 # flip the bit at that column
return r, pos + 1 # report the 1-based position
msg = [1, 0, 1, 1]
c = encode(msg)
# Single error: flip bit 3 -> corrected
r1 = c.copy(); r1[2] ^= 1
fixed1, pos1 = decode(r1)
print("codeword :", c.tolist())
print("received :", r1.tolist(), "syndrome", ((r1 @ H.T) % 2).tolist())
print("flipped bit position:", pos1, " corrected ok:", np.array_equal(fixed1, c))
# Double error: flip bits 1 and 2 -> miscorrected
r2 = c.copy(); r2[0] ^= 1; r2[1] ^= 1
fixed2, pos2 = decode(r2)
print("double error received:", r2.tolist(), "syndrome", ((r2 @ H.T) % 2).tolist())
print("decoder flips position", pos2, "->", fixed2.tolist(), " ok:", np.array_equal(fixed2, c))Expected output of the Python listing:
codeword  : [1, 0, 1, 1, 0, 0, 1]
received  : [1, 0, 0, 1, 0, 0, 1] syndrome [1, 1, 1]
flipped bit position: 3  corrected ok: True
double error received: [0, 1, 1, 1, 0, 0, 1] syndrome [0, 1, 1]
decoder flips position 4 -> [0, 1, 1, 0, 0, 0, 1]  ok: False
FAQ
What errors can the (7,4) Hamming code correct? Any single-bit error in a 7-bit codeword. A double error produces a nonzero syndrome that matches some single-error syndrome, so the decoder flips the wrong bit (see the double-error example above). Extended Hamming codes or CRCs are used when double-error detection matters. Bursts of errors are a different problem: interleavers spread a burst across many codewords so that each codeword sees only single errors.
What is the syndrome, and how does decoding use it? The syndrome is $\mathbf{r}\,\mathbf{H}^T$. A zero syndrome means no error was detected. A nonzero syndrome matches one column of $\mathbf{H}$, and that column’s position is the bit to flip. In the position-ordered form of $\mathbf{H}$, the syndrome read as a binary number is the error position.
Does Hamming decoding use hard bits or soft values? The classic algorithm works on hard 0/1 decisions. Soft-decision and maximum-likelihood decoding use channel log-likelihood ratios with the same parity structure to get more coding gain. See the hard vs soft and maximum-likelihood articles in the learning path above.
Is Hamming code used in modern systems? Not for the main data channel. Current cellular standards use stronger codes: 5G NR specifies LDPC codes for data and polar codes for control information in TS 38.212. Hamming codes remain common in memory and storage, where their low complexity matters.
Similar articles
- Hard and soft decision decoding
- Maximum-likelihood decoding
- Shannon channel capacity formula
- BPSK BER vs Eb/N0 in Python and Matlab
References
[1] R. W. Hamming, “Error detecting and error correcting codes,” Bell System Technical Journal, 29(2): 147–160, 1950. DOI
[2] Stephen B. Wicker, Error Control Systems for Digital Communication and Storage, Prentice Hall, 1995, ISBN 0132008092.
Hello. I like your books and is planning to purchase all three. But when I worked out the problem by hand and refer to https://en.wikipedia.org/wiki/Hamming_code, there are some discrepancies. My work is in line with https://en.wikipedia.org/wiki/Hamming_code.
My method starts with a truth table to get the booleon equations, and the venn diagram, the generator matrix and the H matrix, etc..
Please comments on your approach.
Thank you
Mong
Thanks for commenting. My aim is not to repeat the theoretical approach that you find in authoritative texts on coding theory. Rather, this is an intuitive approach to understand the idea behind code construction.
Thanks!