Link budget path:
Friis free space →
Log-distance / shadowing →
Two-ray ground →
FSPL calculator
In one sentence: Beyond a clear LOS Friis link, log-distance path loss predicts $latex P_L(d)$ with an environment-dependent exponent $latex n$ and optional log-normal shadowing $latex \chi$.
Log distance path loss model
Log distance path loss model is an extension to the Friis free space model. It is used to predict the propagation loss for a wide range of environments, whereas, the Friis free space model is restricted to unobstructed clear path between the transmitter and the receiver. The model encompasses random shadowing effects due to signal blockage by hills, trees, buildings etc. It is also referred as log normal shadowing model.
In the far field region of the transmitter, for distances beyond$latex d_f$, if$latex P_L(d_0)$ is the path loss at a distance$latex d_0$ meters from the transmitter, then the path loss at an arbitrary distance$latex d>d_0$ is given by

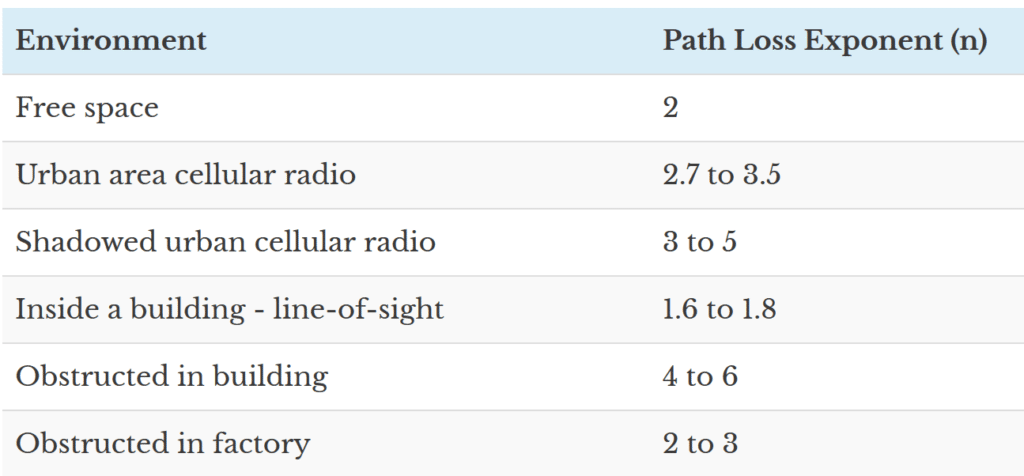
where,$latex P_L(d)$ is the path loss at an arbitrary distance$latex d$ meters,$latex n$ is the path loss exponent that depends on the type of environment, as given in Table below. Also,$latex \chi$ is a zero-mean Gaussian distributed random variable with standard deviation$latex \sigma$ expressed in$latex dB$, used only when there is a shadowing effect. The reference path loss$latex P_L(d_0)$, also called close-in reference distance, is obtained by using Friis path loss equation (equation 2 in this post) or by field measurements at$latex d_0$. Typically,$latex d_0=1m$ to$latex 10m$ for microcell and$latex d_0 = 1\;Km$ for a large cell.
The path-loss exponent (PLE) values given in Table below are for reference only. They may or may not fit the actual environment we are trying to model. Usually, PLE is considered to be known a-priori, but mostly that is not the case. Care must be taken to estimate the PLE for the given environment before design and modeling. PLE is estimated by equating the observed (empirical) values over several time instants, to the established theoretical values. Refer [1] for a literature on PLE estimation in large wireless networks.
logNormalShadowing.m: Function to model Log-normal shadowing (Refer the book for the Matlab code – click here)
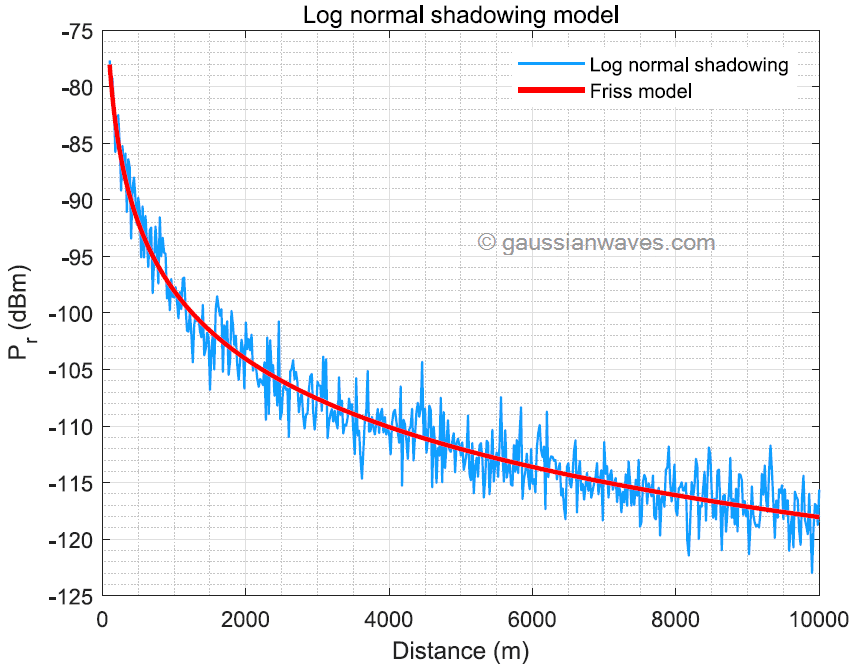
The function to implement log-normal shadowing is given above and the test code is given next. Figure 1 shows the received signal when there is no shadowing effect and the case where shadowing exists. The r
The function to implement log-normal shadowing is given above and the test code is given next. Figure 1 above shows the received signal power when there is no shadowing effect and the case when shadowing exists. The results are generated for an environment with PLE n = 2, frequency of transmission f = 2.4 GHz, reference distance d0 = 1 m and standard deviation of the log-normal shadowing σ = 2dB. Results clearly show that the log-normal shadowing introduces randomness in the received signal power, which may put us close to reality.
log_distance_model_test.m: Simulate Log Normal Shadowing for a range of distances
Pt_dBm=0; %Input transmitted power in dBm
Gt_dBi=1; %Gain of the Transmitted antenna in dBi
Gr_dBi=1; %Gain of the Receiver antenna in dBi
f=2.4e9; %Transmitted signal frequency in Hertz
d0=1; %assume reference distance = 1m
d=100*(1:0.2:100); %Array of distances to simulate
L=1; %Other System Losses, No Loss case L=1
sigma=2;%Standard deviation of log Normal distribution (in dB)
n=2; % path loss exponent
%Log normal shadowing (with shadowing effect)
[PL_shadow,Pr_shadow] = logNormalShadowing(Pt_dBm,Gt_dBi,Gr_dBi,f,d0,d,L,sigma,n);
figure;plot(d,Pr_shadow,'b');hold on;
%Friis transmission (no shadowing effect)
[Pr_Friss,PL_Friss] = FriisModel(Pt_dBm,Gt_dBi,Gr_dBi,f,d,L,n);
plot(d,Pr_Friss,'r');grid on;
xlabel('Distance (m)'); ylabel('P_r (dBm)');
title('Log Normal Shadowing Model');legend('Log normal shadowing','Friss model');
References
Topic in this chapter
- Introduction to Large scale propagation models
- Friis free space propagation model
- Log distance path loss model
- Two ray ground reflection model
- Modeling diffraction loss
- Hata Okumura model for outdoor propagation
FAQ
What is the log-distance path-loss formula? A common model is $latex P_L(d)=P_L(d_0)+10n\log_{10}(d/d_0)+\chi$ in dB, where $latex n$ is the path-loss exponent and $latex \chi$ is an optional log-normal shadowing term ($latex \chi\sim\mathcal{N}(0,\sigma^2)$). Distance $latex d_0$ is a reference (often 1 m or 100 m) at which path loss is known from measurement or Friis.
What does the path-loss exponent n mean in practice? It is the slope of loss versus log-distance: about 2 in free space, higher in cities or indoors where clutter absorbs and scatters energy. Published tables are only starting points — a site survey or drive test is what calibrates $latex n$ and $latex \sigma$ for a real deployment.
When should I use Friis instead of log-distance? Use Friis for clear line-of-sight free-space links that match its assumptions. Switch to log-distance (with or without shadowing) when the environment is cluttered, when you need a statistical fade margin, or when measured exponents deviate from 2.
how I can generate the shadowing samples at different locations in a cell when they are not independent , there is a correlation distance between them .
Check this out
https://www.gaussianwaves.com/2014/07/generating-correlated-random-numbers/
How i can generate Hata Model for (1) Urban (2)Rural area when ht=30m ,hr=1m ,f=800Mhz and distance is 10 t0 200m…. plz snd me coding
Dear Mr. Mathuranathan Sir,
May you please share the “log distance path loss matlab code” thanks
Mirza Ferdous Rahman
log distance path loss model having a attenuation factor matlab code kindly help me
How can we calculate the shadowing effect Xsigma ? It is said that it zero mean gaussian random variable, but variance is considered in the equation. How is this possible?
The graph above was generated assuming mean=0 and sigma=2 dB for the underlying normal distribution.