Fisher information is a single number that tells you how sharply the data reveal an unknown parameter. The sharper the likelihood peak, the more the data say about the parameter, and the better any unbiased estimator can be. This post builds the idea from the score, which is the slope of the log-likelihood, and ends with a Python check you can run yourself.
Likelihood: the data viewed as a function of the parameter
Suppose you have a dataset $x$ and a model $p(x;\theta)$ that depends on an unknown parameter $\theta$. Once the data are fixed, $p(x;\theta)$ becomes a function of $\theta$ alone. This is called the likelihood, written $L(\theta)$. It answers the question: how plausible is each value of $\theta$, given what we saw?
We almost always work with the log-likelihood, $\ln L(\theta)$. Taking the log turns products of independent sample probabilities into sums, and it keeps the same peak. The peak of the log-likelihood is the maximum likelihood estimate (MLE).
The score: the slope of the log-likelihood
The score is the derivative of the log-likelihood with respect to the parameter:
$$u(\theta) = \frac{\partial \ln p(x;\theta)}{\partial \theta}$$
The score is the slope of the log-likelihood curve at the chosen $\theta$. Three facts to remember:
- To the left of the peak the slope is positive, and to the right it is negative.
- At the peak the slope is zero. This is why solving $u(\hat{\theta}) = 0$ gives the maximum likelihood estimate.
- The score depends on the data. Each new dataset gives a different score at the same $\theta$.
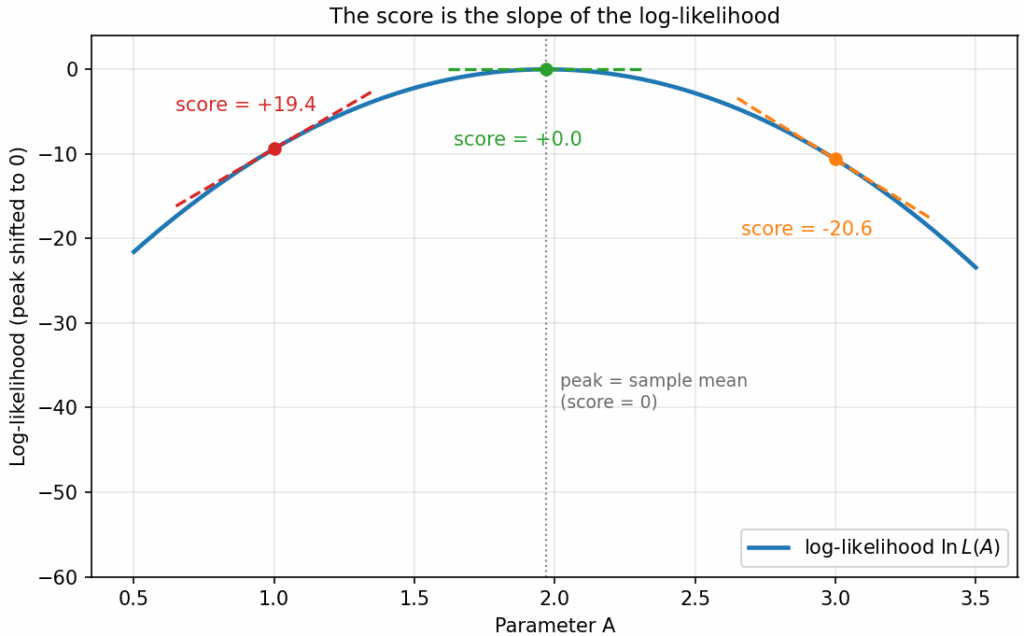
Figure 1: The score at each point is the slope of the curve there. It is positive on the left, zero at the peak, and negative on the right.
The expected score is zero
Evaluate the score at the true parameter value and average over all possible datasets. The result is always zero. Here is why. Because $\partial \ln p/\partial\theta = (\partial p/\partial\theta)/p$, the expectation is
$$E\lbrace u(\theta)\rbrace = \int \frac{1}{p(x;\theta)}\,\frac{\partial p(x;\theta)}{\partial \theta}\,p(x;\theta)\,dx = \frac{\partial}{\partial \theta}\int p(x;\theta)\,dx = \frac{\partial}{\partial \theta}(1) = 0$$
The integral of a probability density is always 1, and its derivative is zero. The score therefore has mean zero, and its spread is what matters next.
Fisher information: the variance of the score
The Fisher information is the expected squared score:
$$I(\theta) = E\left\lbrace u(\theta)^2\right\rbrace $$
Because the mean of the score is zero, this is also the variance of the score. A score that varies a lot from dataset to dataset means the data are very sensitive to $\theta$, so $I(\theta)$ is large.
There is a second, equivalent form. Differentiate $E\lbrace u(\theta)\rbrace = 0$ with respect to $\theta$ and apply the product rule to $u\,p$. This gives $E\lbrace \partial u/\partial\theta\rbrace + E\lbrace u^2\rbrace = 0$, and since $\partial u/\partial\theta = \partial^2 \ln p/\partial\theta^2$:
$$I(\theta) = -E\left\lbrace \frac{\partial^2 \ln p(x;\theta)}{\partial \theta^2}\right\rbrace $$
This is the curvature form. A sharp peak has a large negative second derivative, and that is exactly the large Fisher information. The minus sign is there because the peak curves downward.
An analogy: how precisely can you find a hilltop in fog? The log-likelihood is a hill, and its top is the best parameter value. In thick fog you can only feel the slope under your feet. On a steep, pointed hill the slope changes quickly as you move, so a small step tells you exactly where the top is. On a flat, broad hill the slope barely changes, and you can be far off without noticing. Fisher information measures the steepness of that hill.
Example: the level of a constant in Gaussian noise
Take $N$ samples $x[n] = A + w[n]$ with independent Gaussian noise of variance $\sigma^2$. The log-likelihood gives
$$u(A) = \frac{1}{\sigma^2}\sum_{n=0}^{N-1}\bigl(x[n] – A\bigr)$$
Setting $u(\hat{A}) = 0$ gives $\hat{A} = \bar{x}$, the sample mean. The Fisher information from the variance form is
$$I(A) = E\lbrace u^2\rbrace = \frac{1}{\sigma^4}\,N\sigma^2 = \frac{N}{\sigma^2}$$
The curvature form gives the same result, since $\partial^2 \ln p/\partial A^2 = -N/\sigma^2$ for every dataset. Each sample adds $1/\sigma^2$ of information, and independent samples add up. The more samples, the sharper the peak.
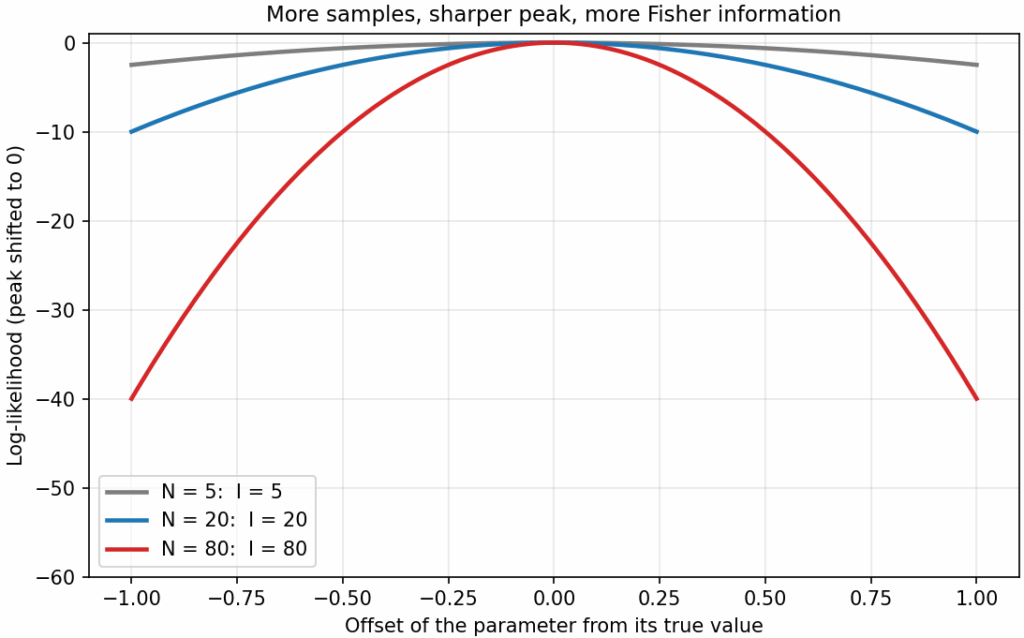
Figure 2: Same noise, more samples. The peak gets sharper, and the Fisher information $I = N/\sigma^2$ grows in proportion to $N$.
Why it matters: the link to the bound
Fisher information sets how well any unbiased estimator can perform. The Cramér-Rao lower bound says that the variance of any unbiased estimator is at least $1/I(\theta)$. A high Fisher information means a low bound, so the data allow precise estimates. A low Fisher information means no estimator, however clever, can be precise. For the constant-level example, the bound is $\sigma^2/N$, which the sample mean reaches exactly.
This is what the title means by estimator sensitivity. Fisher information tells you how sensitive the data are to the parameter, and so how accurately you can ever estimate it.
Python: checking the score and Fisher information
The code below uses one dataset to check the peak and curvature, and then simulates 20,000 datasets to check the mean and variance of the score.
import numpy as np

rng = np.random.default_rng(4)
A_true, sigma, N = 2.0, 1.0, 20
x = A_true + sigma * rng.standard_normal(N)      # one dataset

def log_likelihood(A, data):
    """ln p(x; A) for i.i.d. Gaussian samples, up to a constant."""
    return -np.sum((data - A) ** 2) / (2 * sigma ** 2)

def score(A, data):
    """u(A) = d/dA ln p(x; A)."""
    return np.sum(data - A) / sigma ** 2

# 1) The score at the true value has mean zero; its variance is the Fisher information
trials = 20_000
xs = A_true + sigma * rng.standard_normal((trials, N))
scores = (xs - A_true).sum(axis=1) / sigma ** 2
print("mean of score at true A:", scores.mean().round(3))
print("variance of score      :", scores.var().round(2))
print("analytic N / sigma^2   :", N / sigma ** 2)

# 2) Curvature: -d^2/dA^2 ln p, by finite differences, should equal N / sigma^2
h = 1e-3
second = (log_likelihood(A_true + h, x) - 2 * log_likelihood(A_true, x)
          + log_likelihood(A_true - h, x)) / h ** 2
print("-second derivative (finite difference):", round(-second, 3))

# 3) The score is zero at the maximum-likelihood estimate, which is the sample mean
A_hat = x.mean()
print("score at sample mean is zero:", np.isclose(score(A_hat, x), 0.0))
print("sample mean:", round(A_hat, 3))Running it prints:
mean of score at true A: 0.015
variance of score      : 19.91
analytic N / sigma^2   : 20.0
-second derivative (finite difference): 20.0
score at sample mean is zero: True
sample mean: 1.969The score averages to zero, its variance is close to $N/\sigma^2 = 20$, and the curvature matches the same value. The score vanishes at the sample mean, which is the maximum likelihood estimate.
Three common misunderstandings
- “Fisher information is a property of one dataset.” It is an average over all possible datasets, evaluated at a given $\theta$. The observed curvature from one dataset is a related but different quantity.
- “A zero score always means a maximum.” It means a stationary point. It can be a maximum, a minimum or a flat spot, so check the curvature as well.
- “More Fisher information always means a better estimator.” It means a lower bound on the variance. Whether a given estimator reaches that bound is a separate question.
What comes next
With the score and Fisher information in hand, the next steps are the maximum likelihood estimation post, which uses the score to find the estimate, and the Cramér-Rao bound introduction, which turns Fisher information into a limit on variance. The efficient estimators post covers the estimators that reach the limit.
Summary
- The likelihood is the probability of the data as a function of the parameter. Its log is the log-likelihood.
- The score is the slope of the log-likelihood. Its mean is zero at the true parameter value.
- Fisher information is the variance of the score, which equals the negative expected curvature of the log-likelihood.
- Independent samples add their Fisher information. For a constant in Gaussian noise, $I = N/\sigma^2$.
Learning path: Estimation theory
- Estimation theory introduction
- Maximum likelihood estimation
- Fisher information and the score (this post)
- Cramér-Rao lower bound introduction
- Minimum-variance unbiased estimators
- Efficient estimators and the CRLB
References
- Fisher information (Wikipedia): the definition, both forms, and multi-parameter extensions.
- Score (statistics) (Wikipedia): the score function and its mean zero property.
- Likelihood function (Wikipedia): the likelihood and its role in inference.
- Maximum likelihood estimation (Wikipedia): using the score to find the estimate.
- Observed information (Wikipedia): the curvature evaluated at the observed data, as opposed to its expectation.
- Steven M. Kay, Fundamentals of Statistical Signal Processing, Volume I: Estimation Theory, Prentice Hall, 1993. Catalog record. A standard textbook on scores, Fisher information and the bound.
Estimation and detection in communications. The same likelihood and curvature tools drive channel estimation, timing recovery and detection in digital receivers. The GaussianWaves eBooks cover some of that classical side with runnable Python and Matlab code.